
Have you ever wondered how global applications run seamlessly without crashing during massive traffic spikes? Cloud computing architecture and distributed systems form the backbone of modern digital infrastructure by pooling resources and spreading workloads across multiple connected servers. This comprehensive guide explores how these systems achieve high availability, scalability, and fault tolerance to power today's applications.
Defining Cloud Computing Architecture and Distributed Systems
What is Cloud Computing Architecture?
Cloud computing architecture refers to the components and sub-components required for cloud computing, typically involving a front-end platform, back-end platforms, a cloud-based delivery network, and a vast central server. It enables users to access data and applications from anywhere via the internet, shifting the hardware burden away from local machines to massive, centralized data centers.
Key Characteristics of Distributed Systems
A distributed system is a collection of independent computers that appear to users as a single coherent system. Key characteristics include concurrency, where components execute tasks simultaneously, and the lack of a global clock, meaning nodes must coordinate messages carefully. Furthermore, these systems are designed to handle independent failures gracefully without bringing down the entire network.
Core Technical Principles of Scalability and Load Balancing
Horizontal Versus Vertical Scaling
To handle growing user bases, systems typically scale in one of two ways. Vertical scaling involves adding more power (CPU, RAM) to an existing server, which eventually hits physical hardware limits. Horizontal scaling, conversely, adds more machines to your resource pool, distributing the load across a larger cluster and offering virtually limitless expansion potential.
Mechanisms of Load Balancing
Load balancers act as the traffic cops of cloud environments. By distributing incoming network traffic across multiple backend servers, they prevent any single server from becoming a bottleneck. Algorithms range from simple round-robin routing to complex dynamic routing based on current server response times and active connections.
Fault Tolerance and Redundancy
Fault tolerance ensures that an application continues operating correctly even if one or more components fail. Achieving this requires redundancy—duplicating critical components or data across distinct availability zones so that a hardware failure in one region does not disrupt overall service delivery.
Data Storage and Management in Distributed Environments
The CAP Theorem and Database Trade-offs
Managing state across multiple servers introduces complex challenges governed by the CAP theorem. This principle states that a distributed data store can simultaneously provide only two out of three guarantees: Consistency, Availability, and Partition tolerance. Because network partitions are inevitable in real-world infrastructure, architects must consciously choose whether their applications prioritize strict data consistency or continuous system availability.
Comparing Cloud Architecture Paradigms: Monolithic Versus Microservices
Architectural Trade-offs and Best Practices
When designing cloud applications, developers often choose between monolithic and microservices architectures. A monolithic application bundles all functions into a single unified unit, making initial deployment straightforward but scaling difficult. In contrast, microservices break applications into small, independently deployable services that communicate via APIs. While microservices drastically improve scalability and team velocity, they also introduce operational complexity in monitoring, debugging, and network latency management.
8 Key Expressions
Cloud computing architecture
Distributed systems
Scalability
Load balancing
Fault tolerance
Redundancy
CAP theorem
Microservices
Would you like to adjust this structure or focus on a specific technical domain for your next piece?
Hier ist die Fortsetzung und das Ende des Fachartikels auf Deutsch zur professionellen E-Mail-Danksagung:
3. Der Nachfass-Dank: Professionell nach dem Gespräch oder Interview
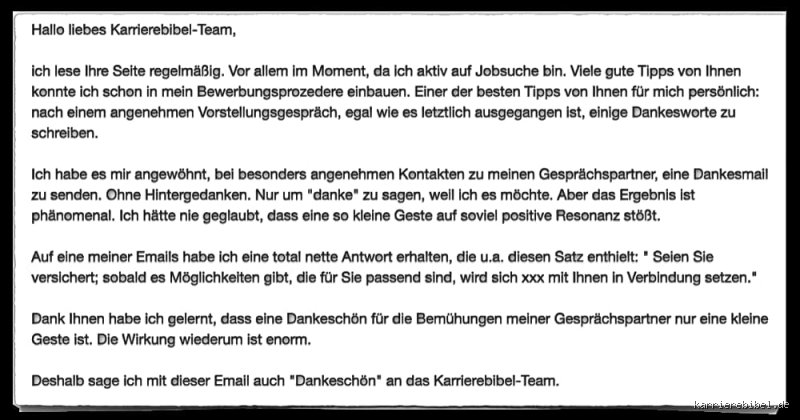
Nach einem Vorstellungsgespräch oder einer wichtigen Verhandlung wirkt eine nachträgliche E-Mail oft wahre Wunder, weil sie echtes Interesse signalisiert. Man sollte diese Nachricht idealerweise innerhalb von vierundzwanzig Stunden versenden, um frisch im Gedächtnis des Gegenübers zu bleiben.
Hierbei empfiehlt sich ein strukturierter Aufbau, der zunächst den konkreten Anlass nennt und sich für die investierte Zeit bedankt. (Ein kurzer Verweis auf ein bestimmtes Detail aus dem Gespräch lockert das Ganze übrigens enorm auf.)
Weil ein solches Nachfassen nicht aufdringlich wirken darf, beschränkt man sich am besten auf wenige Zeilen, die Professionalität und Höflichkeit ausstrahlen.
Im Schlussteil bekräftigt man noch einmal die eigene Motivation für die Zusammenarbeit, ohne dabei ungeduldig nach dem finalen Ergebnis zu drängen.
4. Häufige Stolpersteine und wie man sie vermeidet
Selbst erfahrene Kommunikatoren tappen gelegentlich in klassische Fallen, wenn es um digitale Höflichkeitsformen geht. Übertriebener Pathos wirkt schnell unaufrichtig, während allzu saloppe Formulierungen in einem formellen geschäftlichen Kontext unpassend erscheinen.
Man unterschätzt zudem oft die Wirkung von Rechtschreibfehlern im Betreff oder in der Anrede, weshalb ein gründliches Korrekturlesen vor dem Klick auf den Senden-Button unerlässlich ist.
Wer diese kleinen Fettnäpfchen gekonnt umschifft, hinterlässt bei den Empfängern stets einen bleibenden und vor allem seriösen Eindruck.
Fazit
Eine gut formulierte Dankesmail ist weit mehr als nur eine bloße Formalität, denn sie stärkt nachhaltig beruf